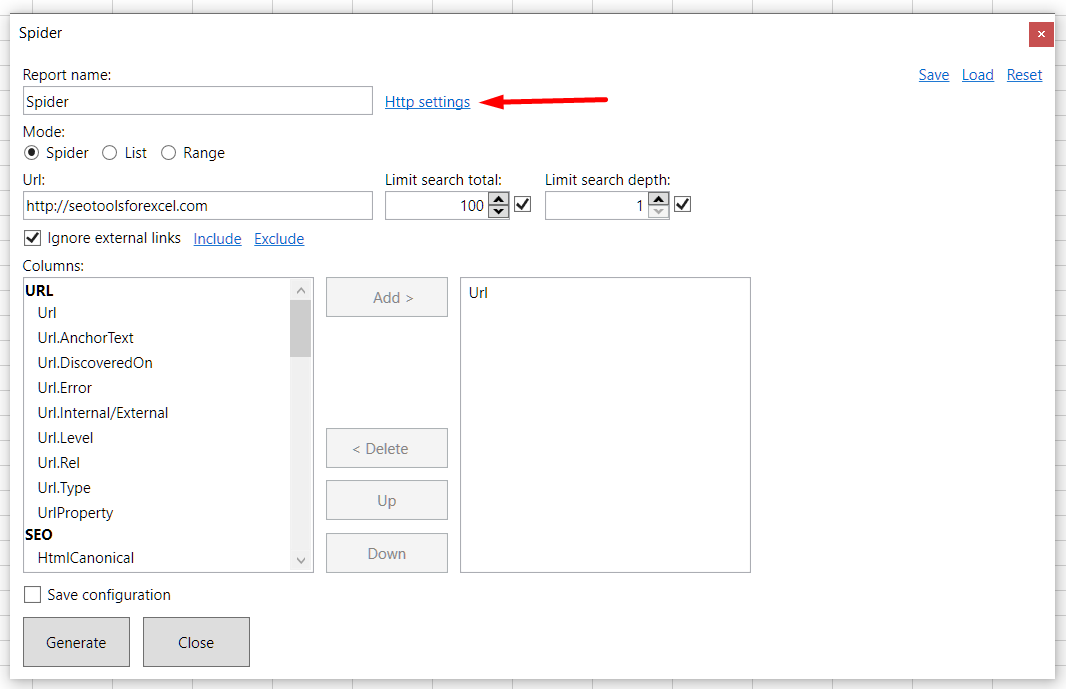
Hi, I used to use Spider on a website to get tons of pages...
I tries again a few minutes ago on the same site but this time nothing works.
I just get one line with no info
I guess the technology hase evolved and the websites protects themselves much better than before ?
Thanks
|Url.AnchorText
|Url.DiscoveredOn => #NUL!
|Url.Error Empty
|Url.Internal/External| => Internal
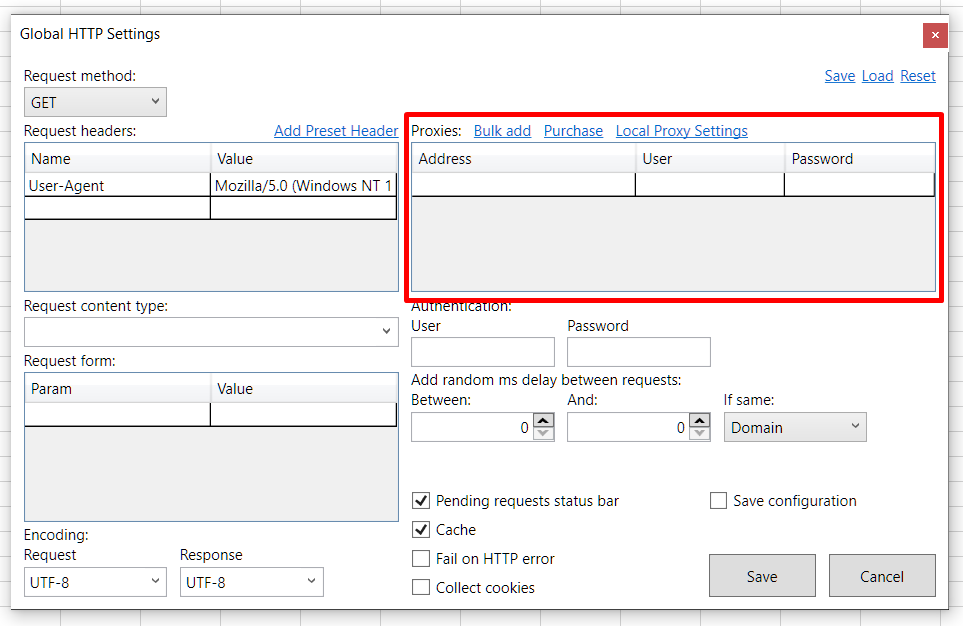
Most likely scraping protection, you can try and set delay or use proxies via the HTTP Settings:
Thanks Viktor. Since I am very poor technically, what do you mean by "use proxies"
For instance on this simple web adress :
https://www.e.leclerc/mag/e-leclerc-paris-19
whatever XpathonUrl I try, I just get a blank cell... No info, nada...
Therefore, I would most appreciate if you make me understand what a proxy is, in that case.
Many, many thanks
Proxies allows you to make requests via another "proxy" computer which helps to avoid scraping protection:
In this case, the website is loaded with javascript after the initial html loads which is accessible using the XPathOnUrl formula.
Sorry twice in advance
- Thanks to show me the Proxies Box: Not sure yet what to write there... especially in terms of address
2.I understand website is loaded with javascript after the initial html loads... BUT I CANNOT ACCESS to it with XPathOnUrl formula... Do you have an example of command that works with xpathonurl and show something ? anything ?
I look very stupid, but it may help other people if you explain slowly and I end up understanding what you wrote...