Hi guys!
I am having issues crawling some pages (like this one: https://www.sundhed.dk/borger/guides/find-behandler/?orgId=51111). When I use SEO Tools to 'Get Text on URL' I can tell that it says I am using an outdated browser.
I tried following the blueprint on this page https://seotoolsforexcel.com/httpsettings/ to change the user agent, but I was not successful. Can anyone else get that to work? I was equally unable to 'extract' any content from that particular page with Screaming Frog (no matter which user agent I choose + told it to render javascript).
Can anyone help with this?  Would be greatly appreciated.
Yeah, that site generates content with javascript and SeoTools doesn't support this (yet!).
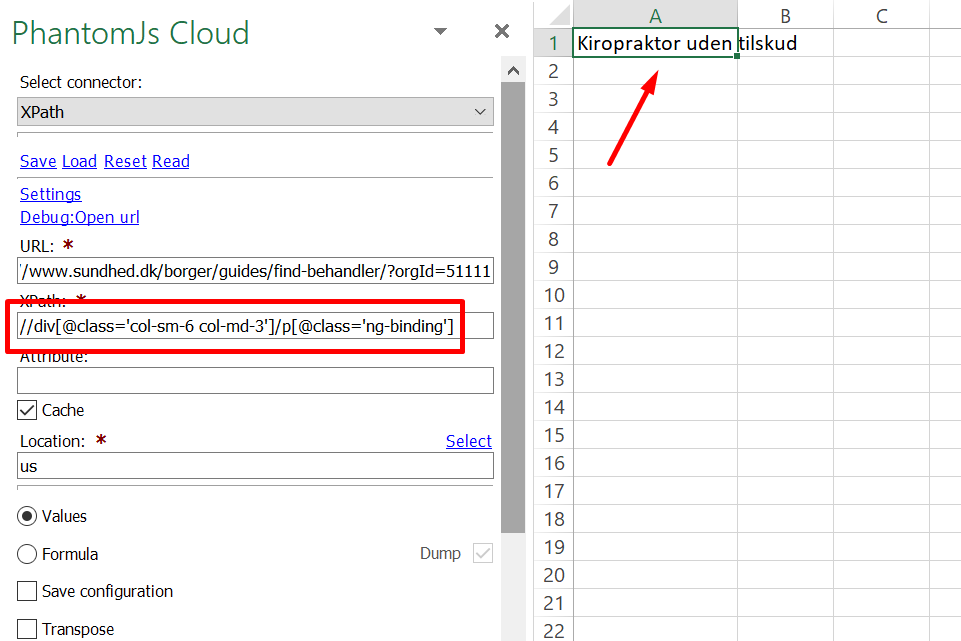
You can use the Phantom JS Connector to grab the content:
Works like a charm Diskborste! Thanks for such a helpful quick relpy!
I went back to my old work and tried to get it to work, but I get a weird message

I have a valid a PhantomJS Cloud API with credits. URL responds, and xpath should be right.. I don't really see how this could go wrong.
Anyone who has an idea? 
It is still working for me. Can you try with another xpath for another site with you know with 100% certainty is correct?
Here is the formula I'm using:
=Connector("PhantomJsCloud.XPath";"https://www.sundhed.dk/borger/guides/find-behandler/?orgId=51111";"//div[@class='col-sm-6 col-md-3']/p[@class='ng-binding']";;TRUE;"us")